Well, these are mutable, but only in the ST or IO monad - which is a guarantee, but at the same time it is not quite the same thing. You cannot just accumulate state by mutating some stuff, then in a separate part of the program mutate it again.
Which is intentional, of course, but quite opposite to the imperative mindset.
About {#- Language Strict #-}, thank you - I was not aware of it.
I think the first example in this post https://markkarpov.com/post/migrating-text-metrics.html makes it clear that, while one can program in imperative style, it is not at all natural, and it is going to introduce as much boilerplate as, say, trying to program in functional style in Java 6
Well, if you want to do full imperative programming with warts and all, you'll probably want to stick to the IO monad for your entire program anyway. You just have to be aware that you're actively handicapping your compiler by choosing to do full imperative programming. (In most other languages, the compilers come handicapped out of the box...)
I think the first example in that post is a bit unfair. The Haskell code is unusually complicated because it avoids a complicated problem that exists in the C code. (Which is that 16-bit encodings can't cover all of UCS-4 with fixed character widths.)
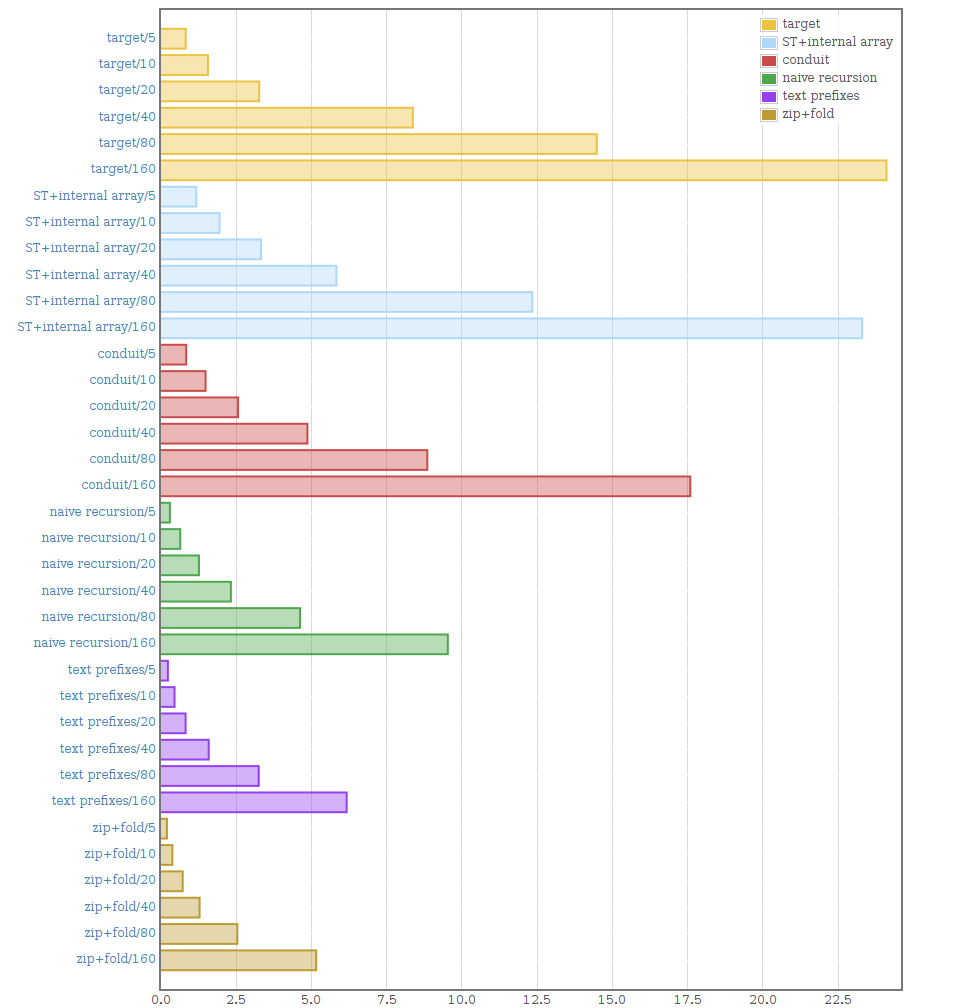
Besides, I don't understand why they are making such a complicated solution. In this comparison [1], the first example in that post is the "target". The best performing solution is... you guessed it:
    foldZip a b =
        List.foldl' (\r (cha, chb) -> if cha /= chb then r+1 else r) 0 (Text.zip a b)
And a pet peeve: the way you say "only in the ST monad" is a funny rhetoric device. You make it sound like everyone agrees it's a bad thing to isolate mutation to local regions. Here's the thing: it's not. And the way you can integrate local mutation in your application with the ST monad is fantastic.
By just typing "ST" a few extra times you get local mutation exactly where you want to, and nowhere you don't want it!
Technically this is only correct if a and b have the same length so you would need to do a length check prior:
    foldZip a b
      | T.length a /= T.length b = Nothing
      | otherwise = foldl' step 0 (T.zip a b)
      where step acc (l, r) = if l == r then acc+1 else acc
This is slightly awkward because T.length is an O(n) operation, though. I think the optimal implementation would be a hyper optimized variant that depends on correct byte alignment and this as slow fallback method if that fails.
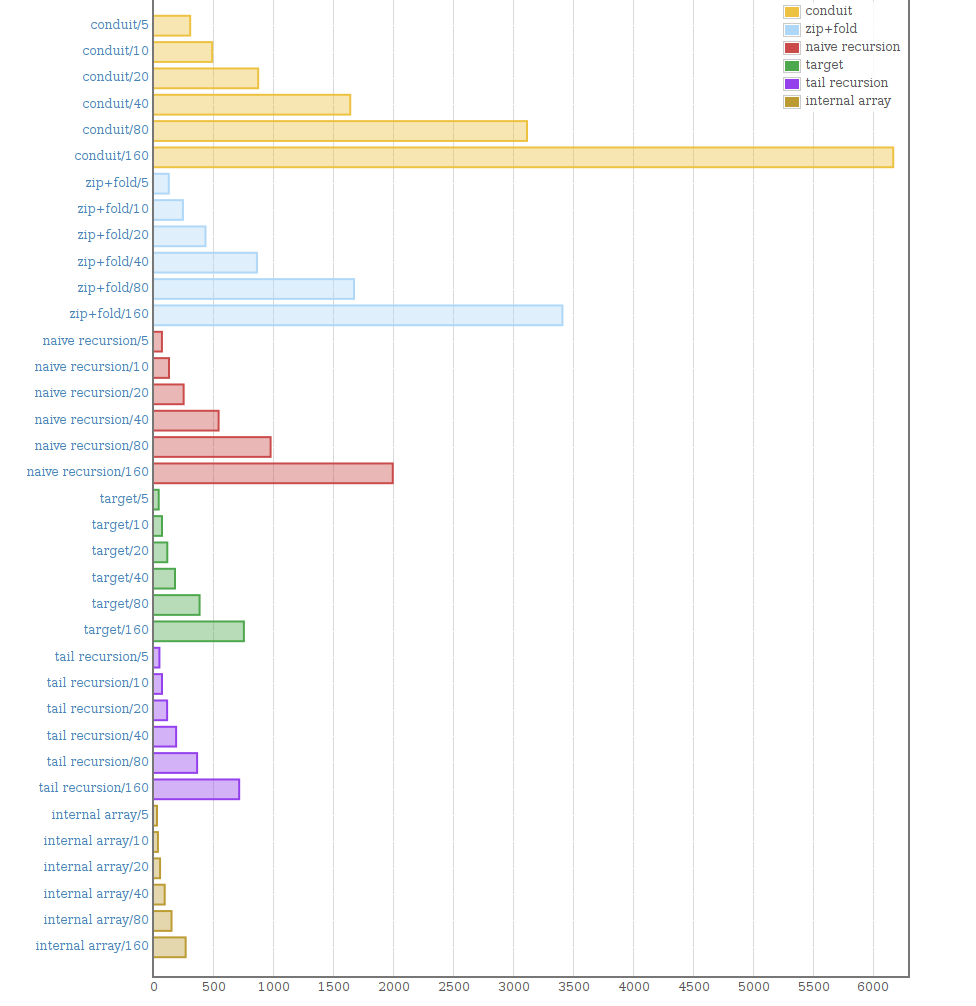
What is fast – without reaching into the Text object internal representation – is good old tail-call recursion. And you can even integrate the length check into the traversal! Making it an O(min(n,m)) operation in total.


Which is intentional, of course, but quite opposite to the imperative mindset.
About {#- Language Strict #-}, thank you - I was not aware of it.
I think the first example in this post https://markkarpov.com/post/migrating-text-metrics.html makes it clear that, while one can program in imperative style, it is not at all natural, and it is going to introduce as much boilerplate as, say, trying to program in functional style in Java 6